
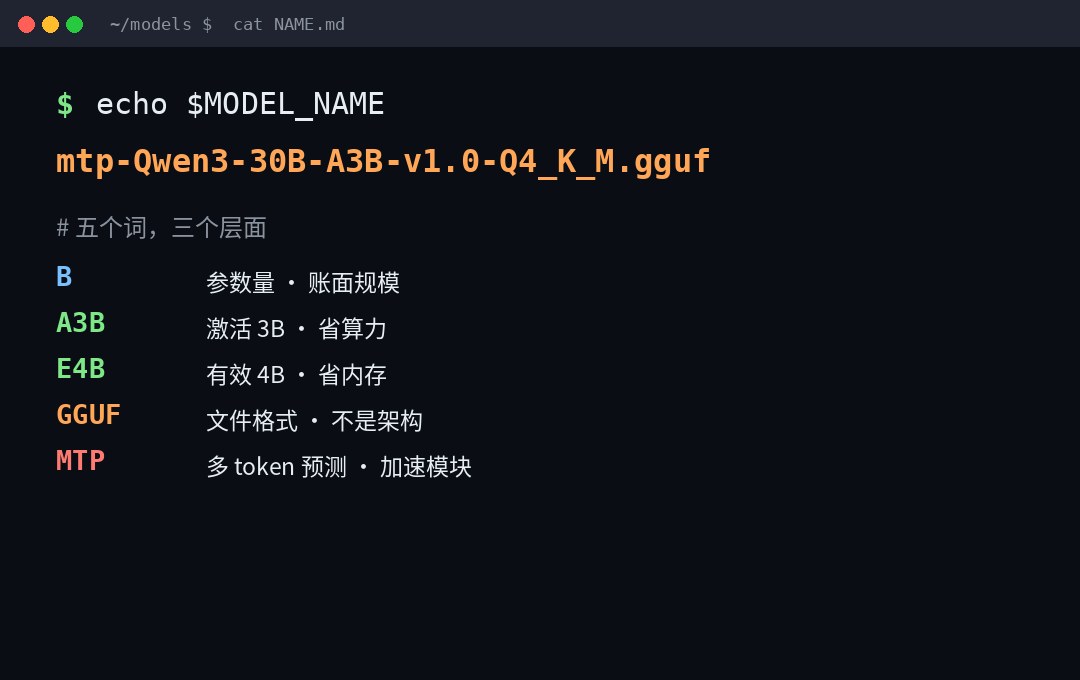
B, GGUF, MTP, A3B, E4B: The five characters in the model name, not one. Yes.
Let's start with a conclusion that saves half of the confusion:These five things are not at all the same dimensions.B is the word, A3B and E4B is the "quantity", GGUF is the container, MTP is the plugin. In fact, they answer an entirely different question.
The specific division of labour is as follows:"B," "How big," "A3B," "How much work," "E4B," "how much is really in the memory," "GGUF," "What is in it," "MTP," "how does it accelerate."Four or five documents appear simultaneously because they do need to be expressed simultaneously — but confusion often occurs when they are treated as the same type of information.
One, B: It's just a billion.
B is Billion, a billion.7B It's a 7 billion-dollar parameter.235B That's 235 billion. It's a set of scale prefixes in the GGUF name code:K ThousandsM Millions,B One billion.T trillions of dollars,Q Billions.
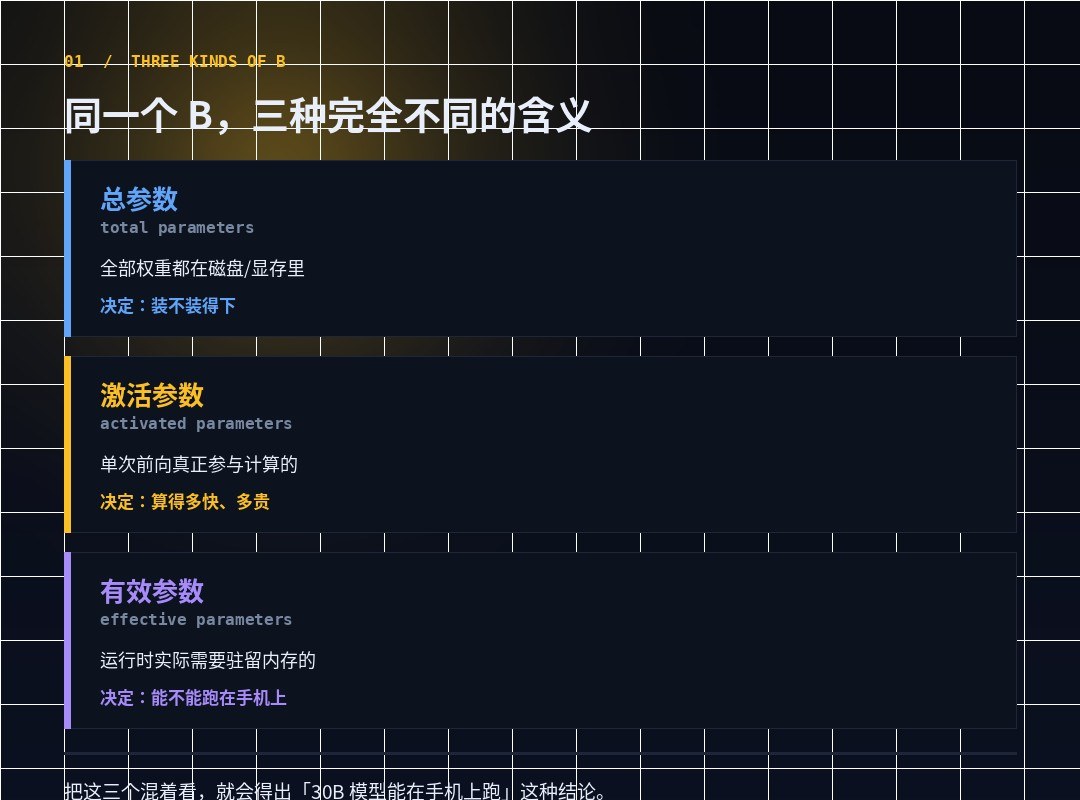
Looks like the simplest one, actually has three completely different meanings. This is the first thing that should be clear:
| Writing | Meaning | Decide what? |
|---|---|---|
30B | Overall parameters: full weight | Can you play it?(disk, visible) |
30B-A3B | Total 30B, single activation 3B | How fast? How expensive? |
E4B | Valid parameters: actual presence at the time of operation | Can you run on the phone? |
If you look at these three lines together, you'll get the conclusion that the 30B model can run on a cell phone.It may be right, but it's not the same as the 30B you thought it was.
II. A3B: General parameters and activation parameters are not a once Yes.
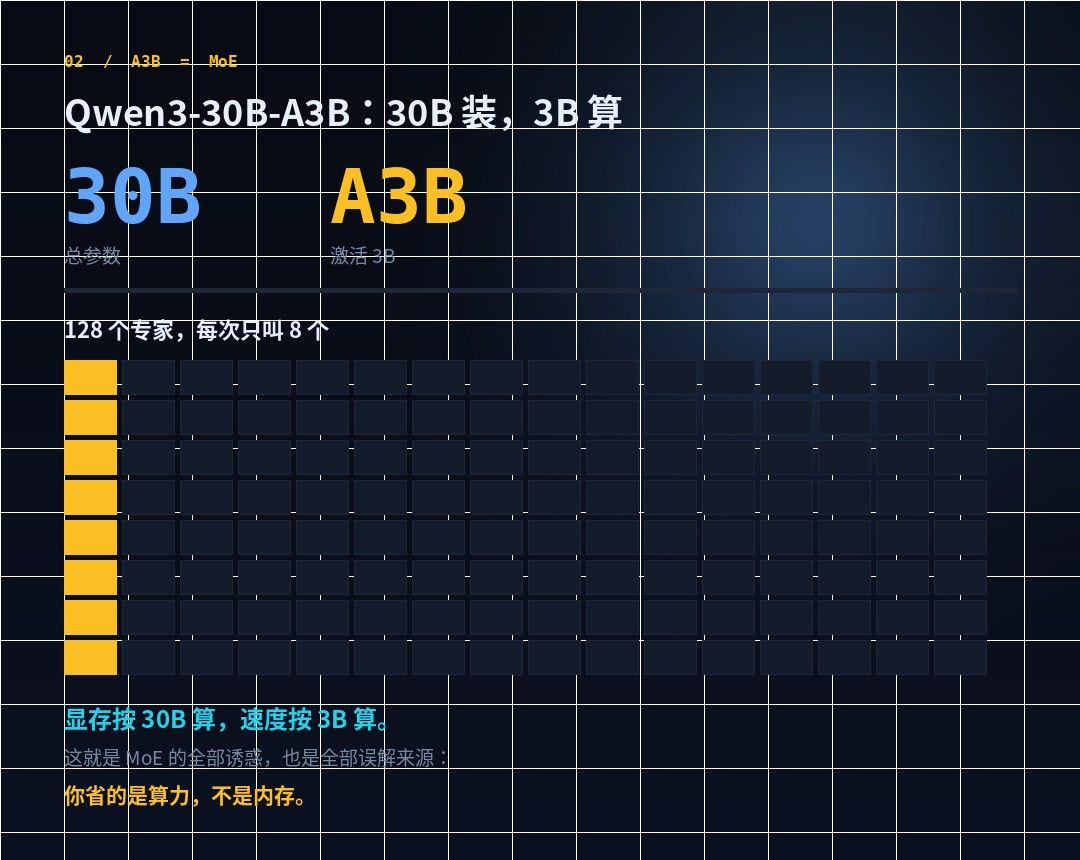
This is from MoE. Qwen3 is very clear about the names of the models:Qwen3-235B-A22B is a large model of "233.5 billion total parameters, 22 billion activated parameters", and Qwen3-30B-A3B is a small MoE of "30 billion total parameters, 3 billion activated parameters".
Technical details are also specific: 30B-A3B has 48 floors, Q/KV head count 32/48 of 128 specialists activated, context 128K. 235B-A22B is 94th floor, 64/4 head, also 128 experts activated 8.
So, A3B, the actual meaning of this mark is:Displays 30B, speed 3B.
That's all the temptation of MoE, all the sources of misunderstanding.You're saving money, not memory.Many people see A3B and think it's a 3B model, loaded on a 4GB machine, and then find it impossible to load. None of the weights are small, but not all of the forward calculations.
Along with an easy to ignore writing: SizeLabel of GGF is <expertCount>x<count><scale-prefix>♪ And so ♪ 8x7B This is called "8 experts x 7B", for a total of 56B.That's either a multiplication ellipsis or a multiplication.Mixtral-8x7B is often misinterpreted as a "7B model" and the actual total parameter is 56B.
III. E4B:E is effictive, not "smaller"
This is one of the easiest to read completely. Gemma 3n's document is clear:
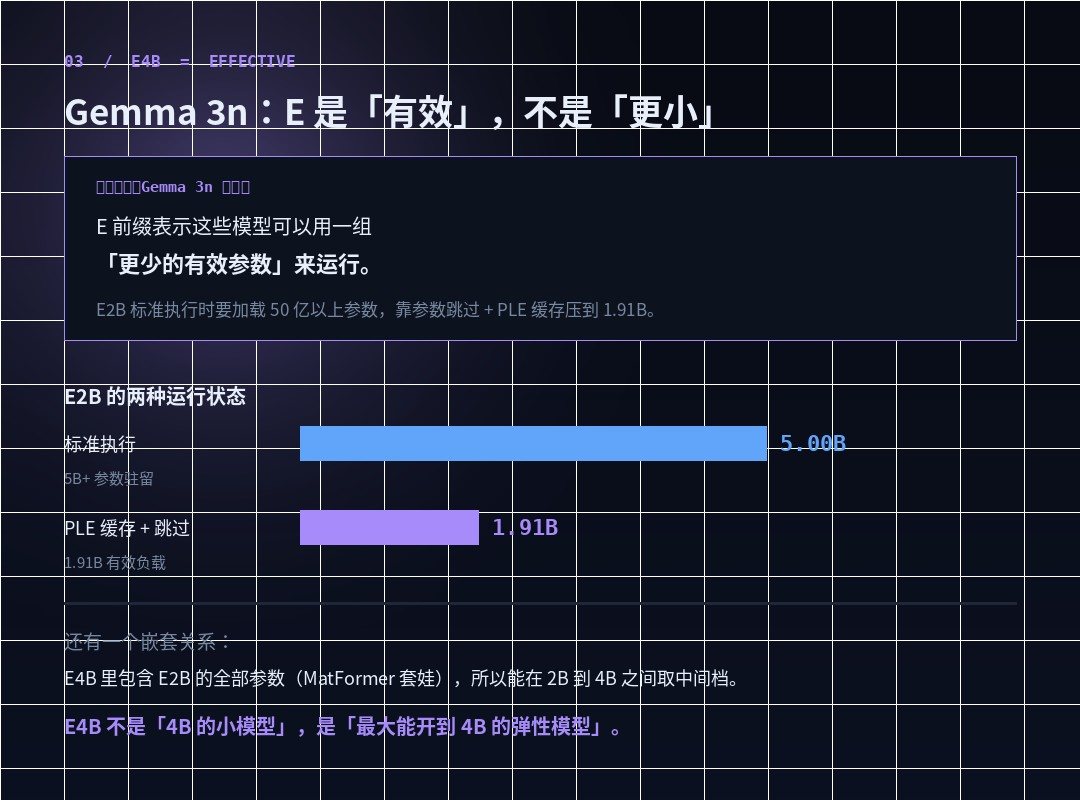
Parameter marks for the Gemma 3n model (e. g. E2B, E4B)Less thanThe total amount of parameters actually included in the model. E prefix indicates that these models can be run with a set of "less active parameters".
To what extent? The document gives the number:E2B standards are implemented by loading more than 5 billion parameters, skipping and PLE caches by parameters to press the active memory load to 1.91B.
Note the main words of this sentence:The model itself has not become smaller, it has become smaller in terms of its presence while running.
This can be achieved through two mechanisms:
- PLE Cache (Per-Layer Embeding).Each layer of embedded parameters can be generated separately from the model memory, cached to a fast local storage, and added to each layer when running.This is equal to asking this part of the parameter out of the memory.
- MatFormer.There are several small models embedded within a large model, which do not need to activate outer parameters when deduced. So you can take any middle between 2B and 4B.
This leads to a counterintuitive fact:E4B contains all E2B parameters.Not two stand-alone models, two slots for the same elastic model. So the exact term is not "E4B is a 4B little model" but "E4B."E4B is an elastic model with maximum power going to 4B.It's not like I'm going anywhere.
This has a great impact on the judgment that "can I run on my equipment":E4B can run E2B-like on low-equipment equipment and expand to 4B on high-equipment equipment.And A3B doesn't have this elasticity -- it's 30B, it's just cost-saving.
IV. GGUUF: It's not a model, it's a model box.
The first three are the size of the model, which has changed the dimensions from GGUF:This is the file format.To be precise, GGUUF is a model storage format for GGML and its implementer (llama.cpp).
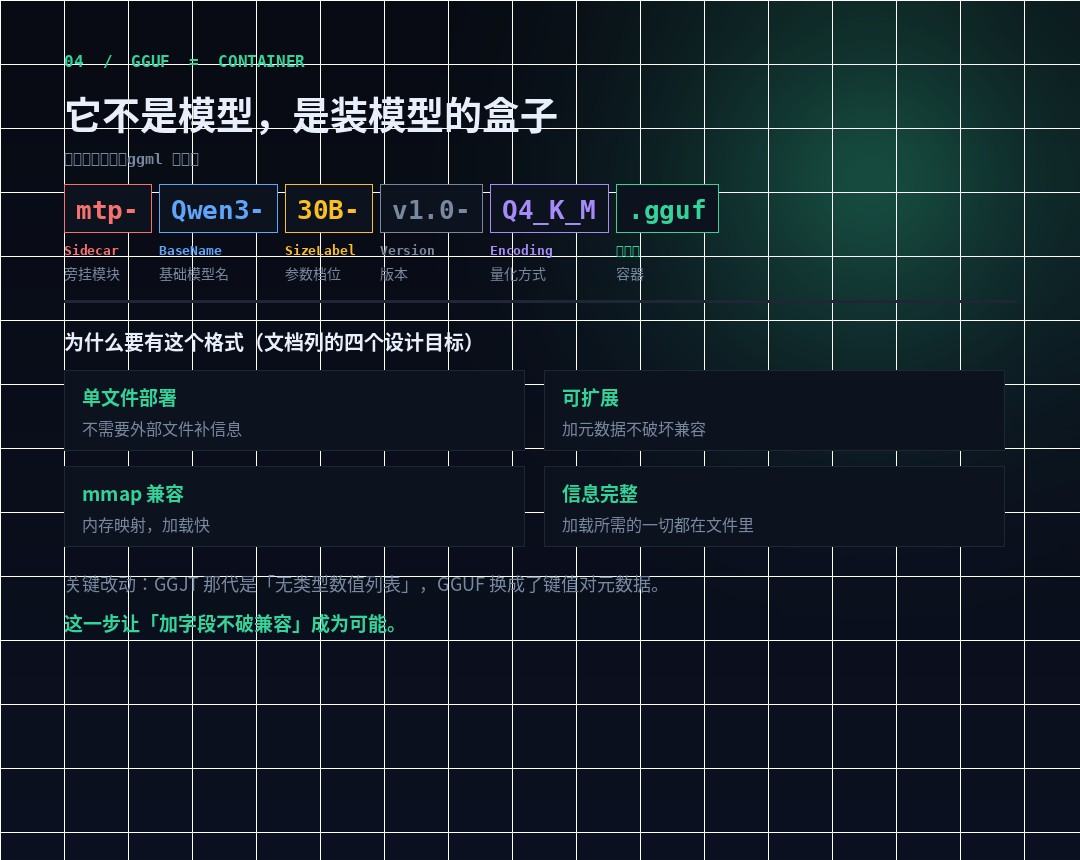
It replaces GGML, GGMF, GGJT, three-generation format. The official design targets are four, each of which corresponds to a past pain point:
| Design objectives | Deal with what? |
|---|---|
| Single file deployment | No additional documentation required, direct distribution and loading |
| Expandable | Adding new metadata does not undermine the compatibility of old models |
mmap Compatibility | Memory Map Loading, quick |
| Complete information | Everything you need to load is in the file. Users don't have to supply it. |
The key difference between it and the last generation of GGJT is just one sentence, but it's the key:The hyperparameter is changed from a list of values without type to a key to metadata.This step made it possible to "add field incompatibility" — once a field had been added, all old solvers had to be changed.
How did you spell it?
The official naming code is:
[].ggufTake a real example.
mtp-Qwen3-27B-v1.0-Q4_K_M.ggufmtp-• Sidecar (byline module, see next section)Qwen3→ BaseName (base model name)27B→ SizeLabel (parameter slot)v1.0Version (version)Q4_K_MEncoding (weight encoding/ quantification)
There are two components that don't often appear to be known:
- Type.:
LoRAIt means it's a adapter, not a complete model;vocabindicates the vocabulary file. - Shad.:
00003-of-00009Shows the fraction, 3rd of 9 Attention.Numbering starts at 00001Not 00000.
There is also an important disclaimer in the norm:It's called "not going to be completely decipherable in the wild.", because the existing gguf file is too diverse.So don't write a regular guess of what's in the file name, read metadata.File general.basenameI don't know.general.size_labelI don't know.general.finetune It's authority.
V. Q4 K M: The longest part of the file name is the compression rate
This is the one that most affects your experience in practice, and the one that no one has made clear.It indicates how much weight has been quantified.
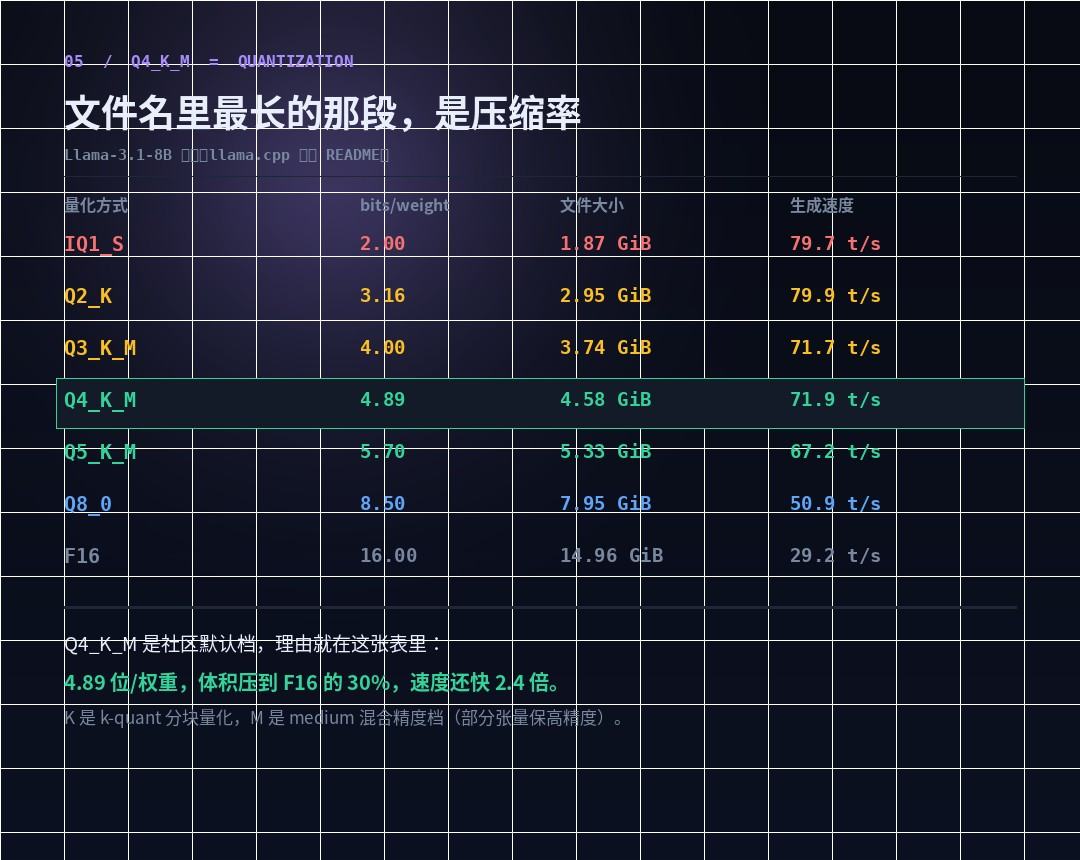
llama.cpp Official README used Llama-3.1-8B to make a factual survey, and I took a couple of steps (original model 32.1 GB):
| Quantification | bits/right | File Size | Generate Speed |
|---|---|---|---|
| IQ1 S | 2.00 | 1.87 GiB | 79.7 t/s |
| Q2 K | 3.16 | 2.95 GiB | 79.9 t/s |
| Q3 K M | 4.00 | 3.74 GiB | 71.7 t/s |
| Q4 K M | 4.89 | 4.58 GiB | 71.9 t/s |
| Q5 K M | 5.70 | 5.33 GiB | 67.2 t/s |
| Q8 0 | 8.50 | 7.95 GiB | 50.9 t/s |
| F16 | 16.00 | 14.96 GiB | 29.2 t/s |
Q4 K M becomes the community default file for all the reasons in this table:4.89 Bits/weights, with a backlog of 30% of F16, which is 2.4 times faster.Up to Q8 0, the volume doubles and drops by 30%, and the quality changes most people do not know; down to IQ1 S, the volume is a little less, and the quality risks are much higher.
How do you read your name?
- Queen = Regular quantification;IQ = The materiality matrix is quantified (i-quant), with better quality and slightly slower speed in the same digits.
- Numbers = target digits. Q4 is 4 bit, Q8 is 8 bit.
- K = k-quant, block quantification (block-wise), older
_0/_1The series is more detailed. - S / M / L = small/media/large, mixed precision slot.M picks out some of the sensitive lids to keep them high.So it's also Q4, K M is slightly bigger than K S.
There is another fact that many people don't know:Quantification can be customized on a case-by-case basis.Official tools support the designation of different types by type, such as: attn_v and ffn_down Sets separately as Q5 K M, while the rest is maintained as Q4 K M; also supports setting by a regular batch number. And that's why the same "Q4 K M" type of file is different from the size of the file that people pressure.It is a default strategy, not a precise specification.
VI. MTP: A small module called "Guess next word"
It's the last one that's easy to use as a model, actually.File Role TagI don't know. In the GGF document mtp Defined as Sidecar (accompanied module), stating:
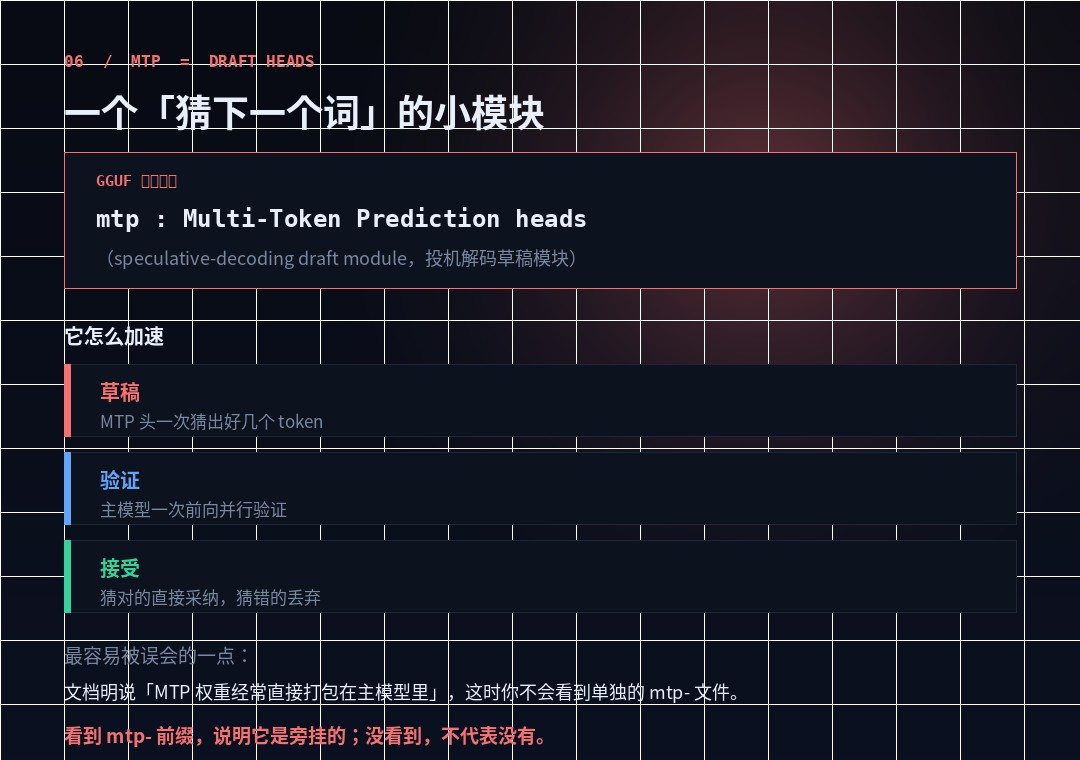
Multi-Token Predation Headers, draft module for speculative decodering, designed to be loaded with base models matching architecture and versions.
It's simple:Let's guess the next few tokens, and let the main model run in parallel.Right direct adoption, wrong drop. Because verification can always confirm multiple tokens, the average drop in time per token -- this is the whole principle of speculative decodering.
But there's a phrase in the document that should be most remembered in this section:"MTP weights are often packed directly into basic models, in which case there is no separate mtp-side file".
So the correct understanding is:Yeah. mtp- Prefixes, indicating that they are on the outside; none seen, does not mean none.That's why looking for MTP in the model list is often not found -- it's already in the main file.
The other Sidecar is... mmproj(multimodal projector, multimodular projector), visual and audio encoder plus projection layer.This is usually a stand-alone document that must be loaded with a base model.So if you put down a multi-mode model of the GGF and you find out you can't see the map, it's probably missing the mmproj file.
VII. Full reading of five characters
All of the above is a complete reading. Suppose you see this file name:
mtp-Qwen3-30B-A3B-v1.0-Q4_K_M.gguf| Snippet | Which floor is it? | Annotations |
|---|---|---|
mtp- | File Role | The attached speculative decodement module needs to match the main model |
Qwen3 | Model Identity | Base Model Name |
30B | Size | Total parameter 30 billion I've decided not to pretend. |
A3B | Calculate | Three billion a time. How fast you decided to run? |
v1.0 | Version | Weight Version |
Q4_K_M | Storage | 4.89 bits/weight, medium mixture precision |
.gguf | Containers | To llama.cpp. |
A summary of the document:A total parameter of 30 billion and a MoE model of 3 billion at a time was pressed to approximately 4.9 places into the GGUUF container, with an additional speculative decoded acceleration module.
VIII. Four of the most common misreads
- Consider A3B as a 3B model.It's not memory. 30B has no less weight, and 4GB is still visible.
- E4B as a "4B small model".It's the largest set of elastic models. E4B contains all the parameters of E2B. Low-fit on it press 2B, not 4B run.
- Use GGF as a model.The same model can be F16, Q8 0, Q4 K M several GGUUFs.GGUF is a container and quantification is content.Asking "Q4 and GGUF good" is like asking "The bottle and the water good."
- This post is part of our special coverage Syria Protests 2011.The official statement that the deal is not entirely legible. Do not write the regular rule to access the metadata of the file with accurate information.
And there's a hidden fifth:Put 8x7B Read 7B.That's "8 experts each 7B." Total 56B. In GGUF <expertCount>x<count> The x is the multiplication.
IX. PURPOSE OF PRACTICAL ADJUSTMENTS
Finally, give a sequence that can be followed. Look at any model name and ask yourself in this order:
- First look at containers and quantify.
.gguf+Q4_K_MThis means that it's a local run-off mass version, and the quality and volume are already set at the time of release. - Read the overall parameters again.Decide whether your presence/RAM is sufficient. It's a hard threshold. It's not enough.
- See if it's Moe.Yes.
A??BDescription is based on activation parameters, but memory is still based on total parameters. - See if there's an E prefix.Yes.
EThis indicates that it is an elastic model and that the actual presence may be well below the nominal value - this determines whether it can access the cell phone. - Last look at Sidecar.Yes.
mmproj-Remember to come together; yes.mtp-Remember matching; neither does it mean that there is no acceleration.
Model name is not a parameter table, but a label. The label works to keep you away from the next wrong file, not to calculate its score.
It's always running. But to read the label correctly, at least you'll know before downloading the 15-GB that it can't be installed...This saved time, more than any benchmark score.